If you want to experiment with LLMs, you typically have a choice of sending your requests to someone else’s computer or fielding a very large GPU and CPU setup to run models locally. However, a recent crop of projects aims to bring bigger models to much more modest hardware.
One example is Strata, a project from [Niko1221], which lets you run a 125-billion-parameter LLM on hardware you might already have for gaming. It won’t run on your old Pentium laptop, but it doesn’t require a supercomputer-like farm of graphics cards, either.
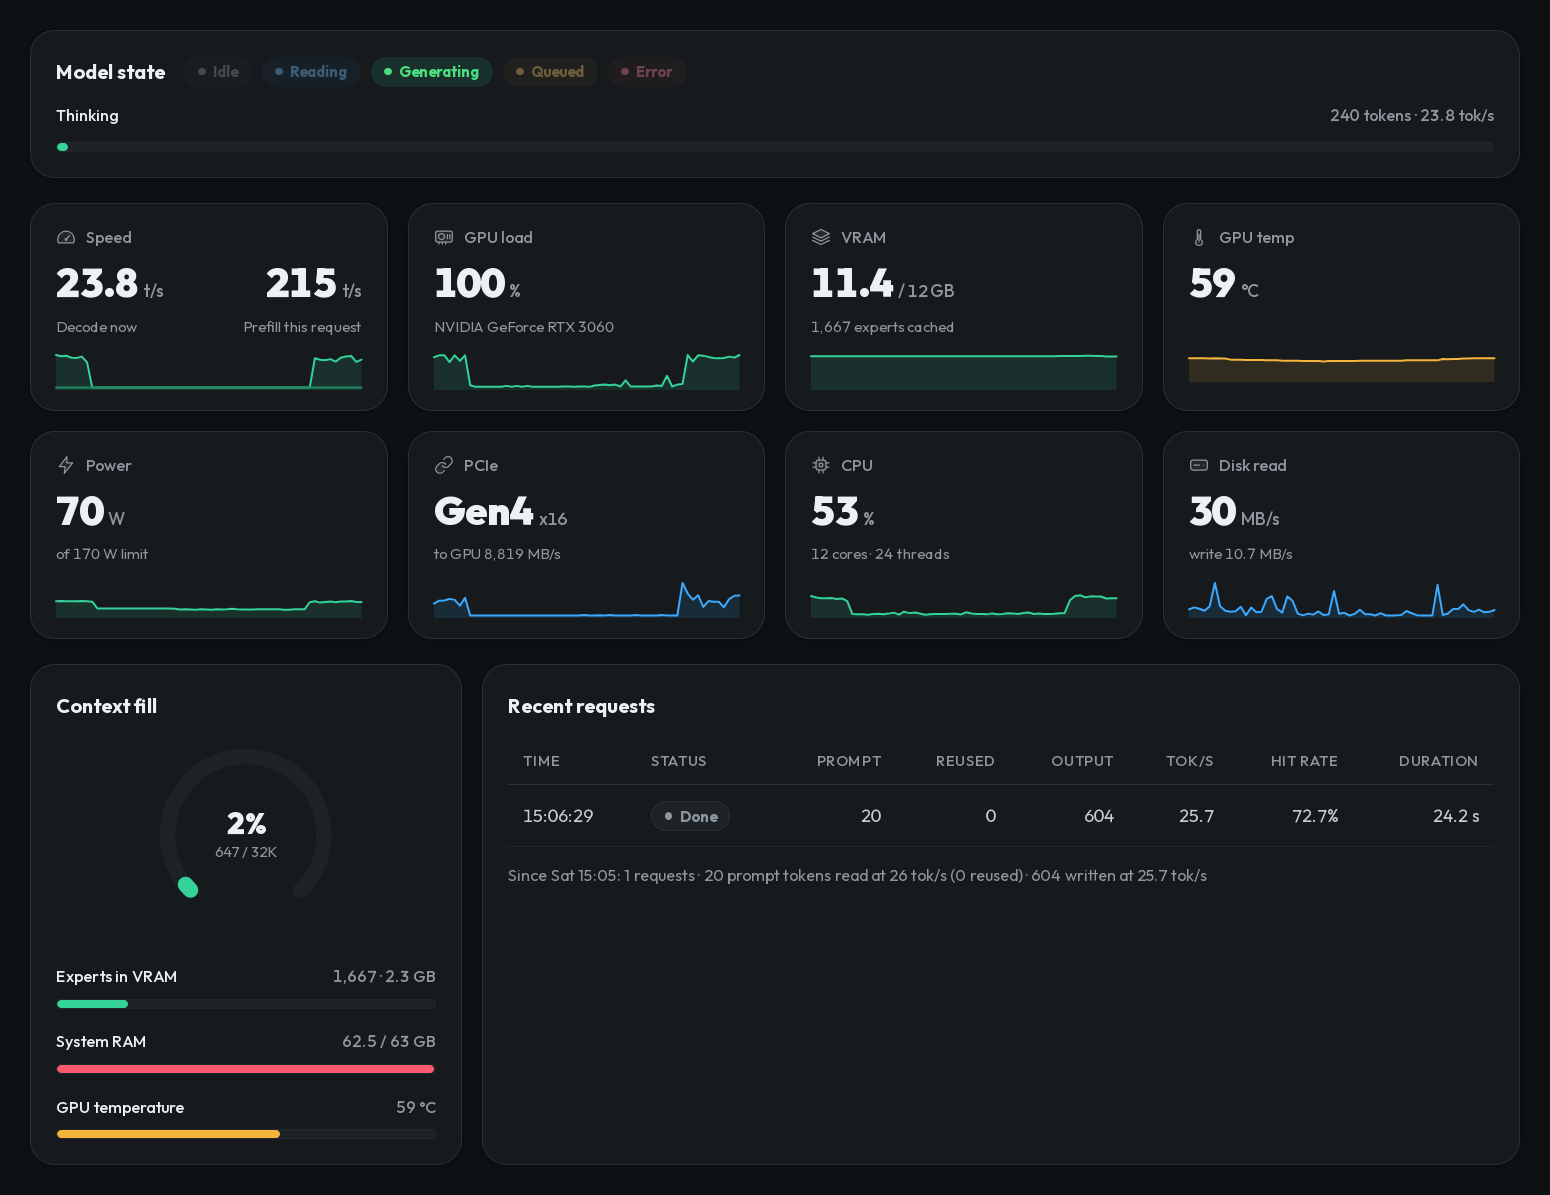
Strata can use several Qwen3.8 model variants, including different quantizations of the original model as well as coding and other specialized versions. Qwen3.8-Flash-Next is a mixture-of-experts model containing 24,576 small experts, of which only ten are needed for each token. The clever part is that Strata effectively treats VRAM as a cache for the much larger model. Frequently used experts stay on the GPU, while the complete collection normally remains in system RAM. The model also includes a roughly 29 GB lookup table that stays on the SSD and is accessed as needed.
The software also uses the model’s multi-token prediction machinery for speculative decoding, allowing several candidate tokens to be checked in a single pass. According to the project, an RTX 5070 with 12 GB of VRAM can produce roughly 50 to 90 tokens per second, depending on quantization. Tokens, of course, aren’t usually entire words, but it is still a respectable clip, once everything gets set up.
We did have some trouble setting everything up due to some incompatibility with the NVIDIA C compiler, our gcc version, and some headers, but your problems will surely be different. The setup.sh file asks you a few questions on the first run. After that, it just handles your selected startup options, which can take a few minutes while everything loads.
Once running, Strata lets you interact through a web browser. It also exposes OpenAI- and Anthropic-compatible APIs on localhost, so existing chat front ends, coding assistants, and other tools can use the local model without much special handling. Of course, you can’t expect its answers to compete with the big models out there for every task. When asking about Hackaday, for example, it got a lot of it right but also got confused about who founded the site and our authors (unless we forgot that [Tom Nardelli] once wrote some posts). Turning up the “thinking level” and turning down the temperature didn’t help much, although it did move its confusion to different facts. It did better when asked to identify some problem code or outline how to port a particular C compiler to a new target.
You’ll still want at least 32 GB of system RAM, 12 GB of VRAM, and around 80 GB of storage, so “modest” is relative. Still, it’s a neat demonstration of how mixture-of-experts models and some clever memory management can stretch ordinary PC hardware surprisingly far.
These economical LLMs can even run on older hardware, just slower.
This articles is written by : Nermeen Nabil Khear Abdelmalak
All rights reserved to : USAGOLDMIES . www.usagoldmines.com
You can Enjoy surfing our website categories and read more content in many fields you may like .
Why USAGoldMines ?
USAGoldMines is a comprehensive website offering the latest in financial, crypto, and technical news. With specialized sections for each category, it provides readers with up-to-date market insights, investment trends, and technological advancements, making it a valuable resource for investors and enthusiasts in the fast-paced financial world.